Web Crawling & Scraping Guides
Calm, practical articles that help developers turn websites into Markdown, cleaned text, or HTML — for LLMs and automation.
Calm, practical articles that help developers turn websites into Markdown, cleaned text, or HTML — for LLMs and automation.
New to crawling or WebCrawlerAPI? These two posts give you the right mental model.
What is an AI Crawl Agent?
AI crawl agents use LLMs to decide what pages to visit and when to stop. Learn how they differ from regular crawlers, when you need one, and when you don't.
What is RAG (Retrieval-Augmented Generation)?
Learn about RAG, a powerful technique that improves AI responses by combining language models with real-time information retrieval, making AI answers more accurate and up-to-date.
What is webcrawling API?
Web crawling API allows developers to retrieve web data efficiently and programmatically, enabling the extraction of content from a website.
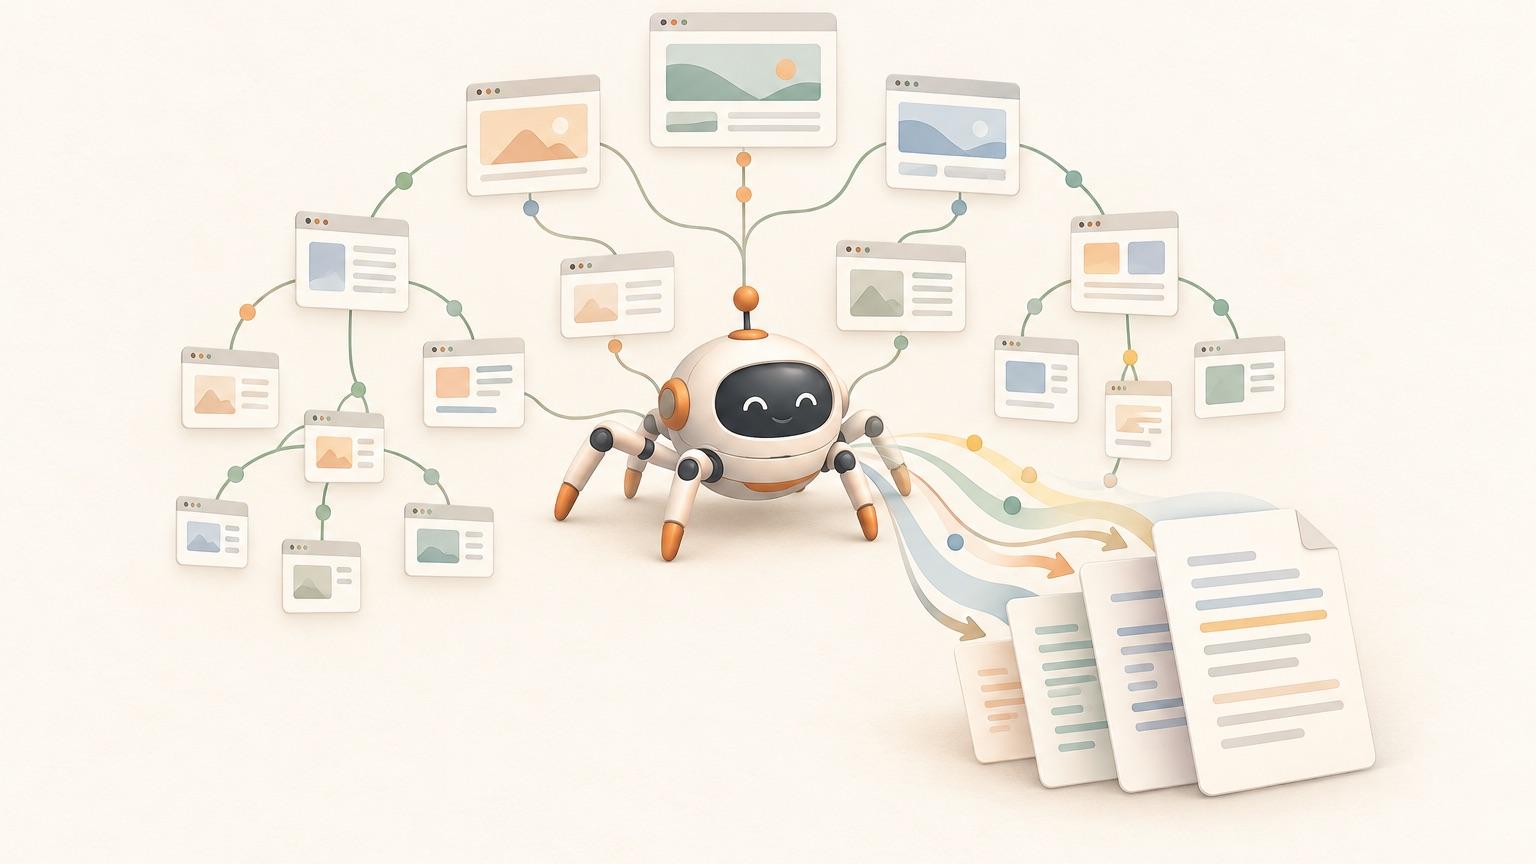
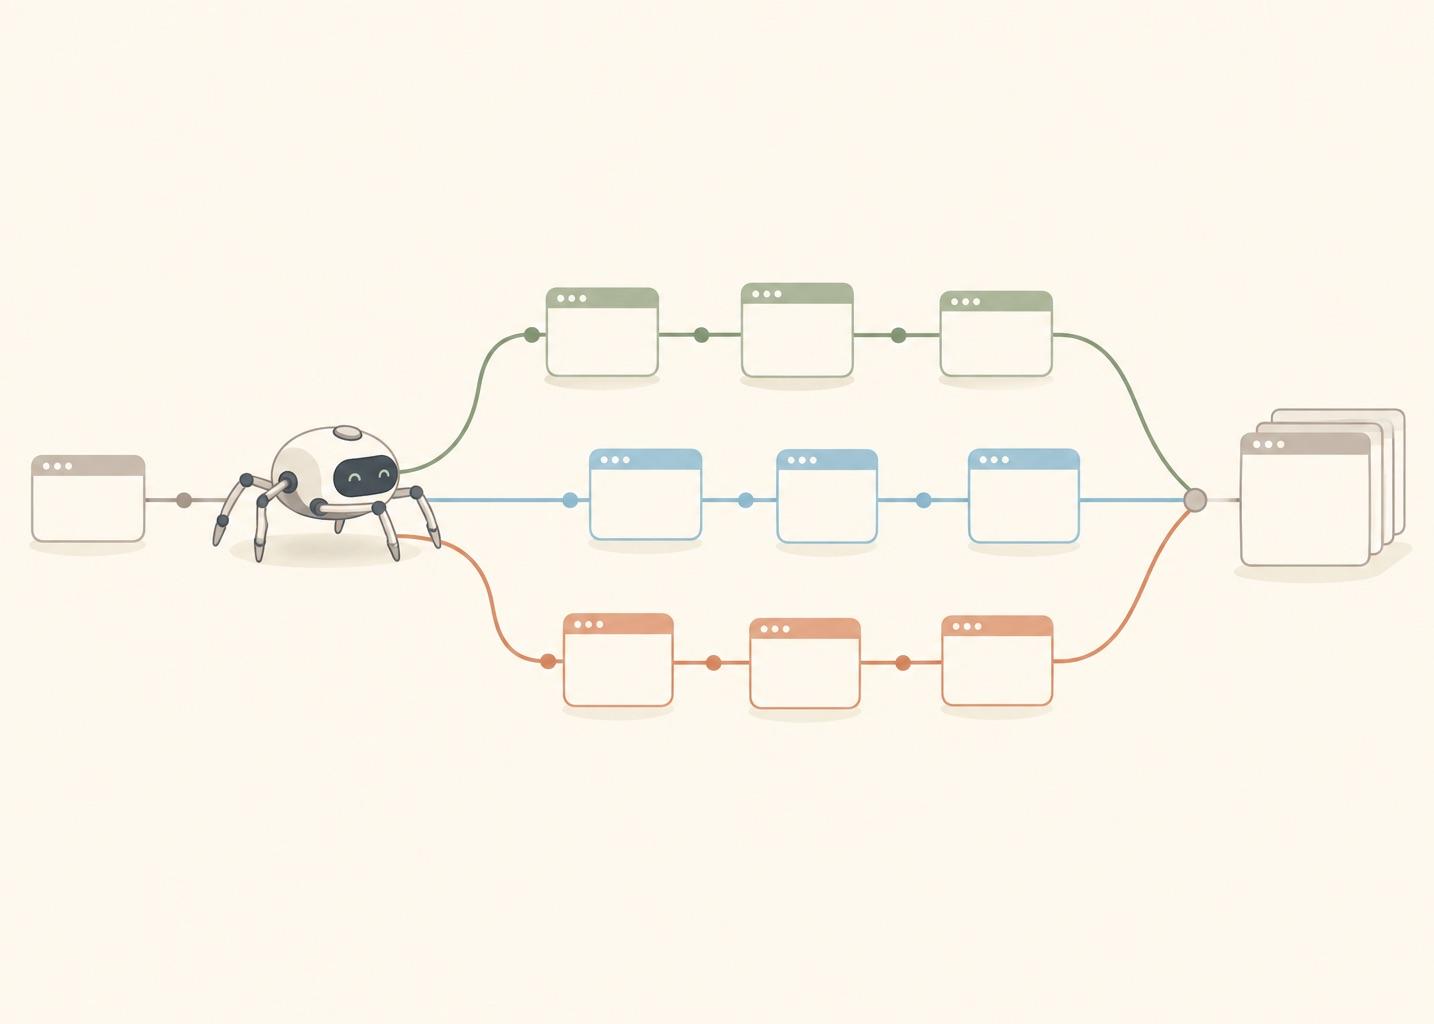
Web crawling finds pages by following links. Web scraping pulls data out of them. See the difference, a real example on one site, and when you need both.
Common workflows teams build with crawling APIs.
Crawl websites into Markdown, cleaned text, or HTML with WebCrawlerAPI — no crawler maintenance.
Everything else — tutorials, comparisons, and technical deep dives.