Last updated: October 18, 2026. I run WebCrawlerAPI, and it is Approach 3 below. Where it loses, I say so.
A Python web crawler is a program that fetches a page, finds the links on it, and follows them. That's the whole idea. The hard parts come after: not fetching the same page twice, not hammering the server, surviving a 500 error, and knowing when to stop.
There are three common ways to build one: a requests + BeautifulSoup loop, a Scrapy spider, or a crawling API. I wrote all three, ran them against the same practice site, and measured speed, code size, duplicates, retries and what happens on a JavaScript page. The numbers are below.
If you only need the data from one known page, read Web Scraping with Python first. This post is about following links across a whole site.
The Short Answer
| requests + BeautifulSoup loop | Scrapy | Crawl API | |
|---|---|---|---|
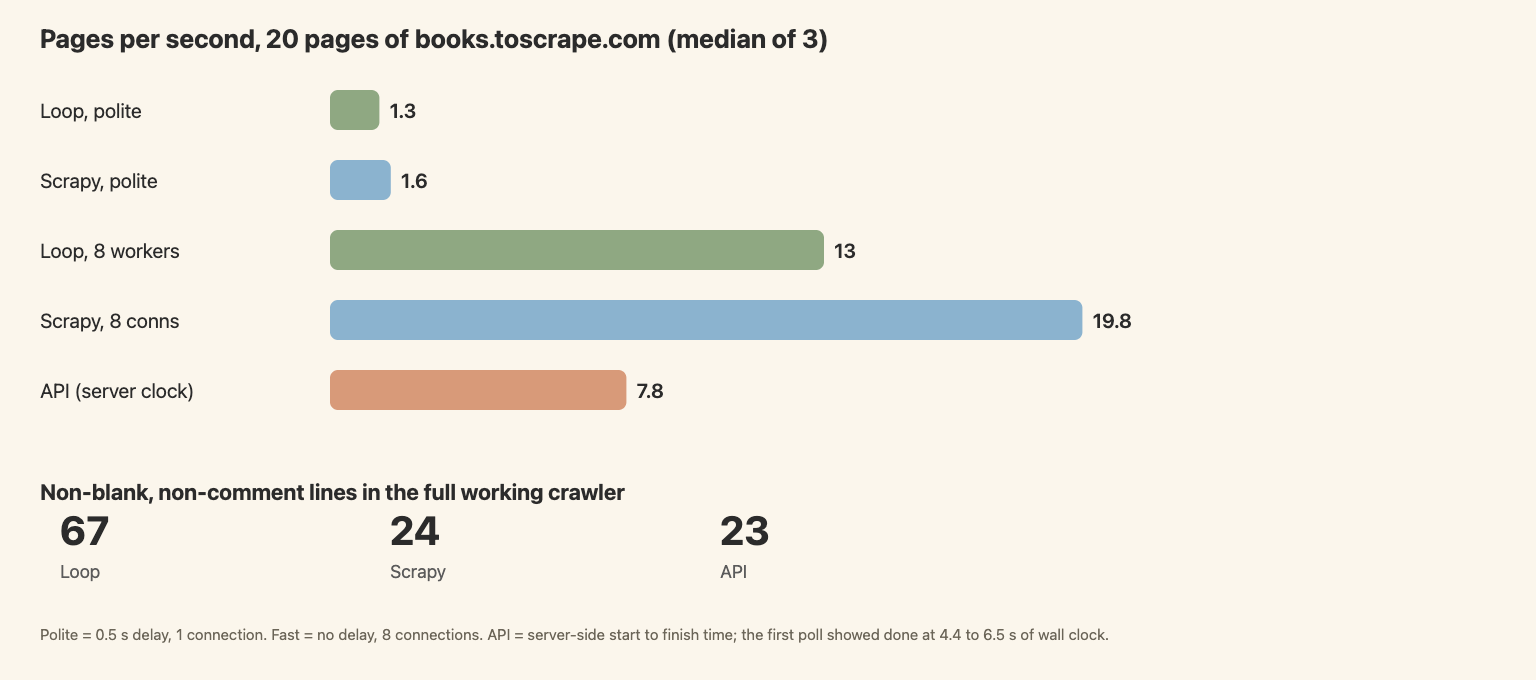
| Pages per second, polite (0.5 s delay) | 1.3 | 1.6 | not tunable (see below) |
| Pages per second, no delay, 8 connections | 13.0 | 19.8 | 7.8 (server clock) |
| Lines of code (working crawler) | 67 | 24 | 23 |
| Duplicate fetches (/ vs /index.html) | 0 after normalizing, 3 without any dedup | 1 | 1 per run |
| Robots.txt by default | you write it | on in a new project, off in a single file | off, set respect_robots_txt |
| Retries | you write it | built in, no backoff | not documented, not tested |
| JavaScript page (quotes.toscrape.com/js/) | 0 quotes | 0 quotes | non-empty Markdown (676 characters, quotes not counted) |
The Scrapy no-delay run (19.8 pages per second) fetched 27 pages, not 20, because requests already in flight keep running after the stop rule fires. The loop fetched 20. That is why I compare pages per second, not total time (details in the Scrapy section below).
My rule after all this: a loop for a small static site, Scrapy when you own the extraction logic and the crawl grows, and an API when pages need rendering or you want Markdown out without running anything. Details and caveats follow.
What a Python Web Crawler Has to Do
Every crawler does the same seven things. If one is missing, you'll find out in production.
- Frontier: a queue of URLs still to visit.
- Normalize: make page#top, page and page/index.html the same URL.
- Seen set: remember what was already queued.
- Robots.txt: check what the site allows.
- Delay: wait between requests so the site isn't hurt.
- Retries and timeouts: survive 500s and slow pages.
- Stop rule: a page limit or depth limit. Otherwise it never ends.
For the design view, see how to build a web crawler and crawl budget. Crawling vs scraping is explained here. Each approach below is checked against this list.
Setup and the Test Site
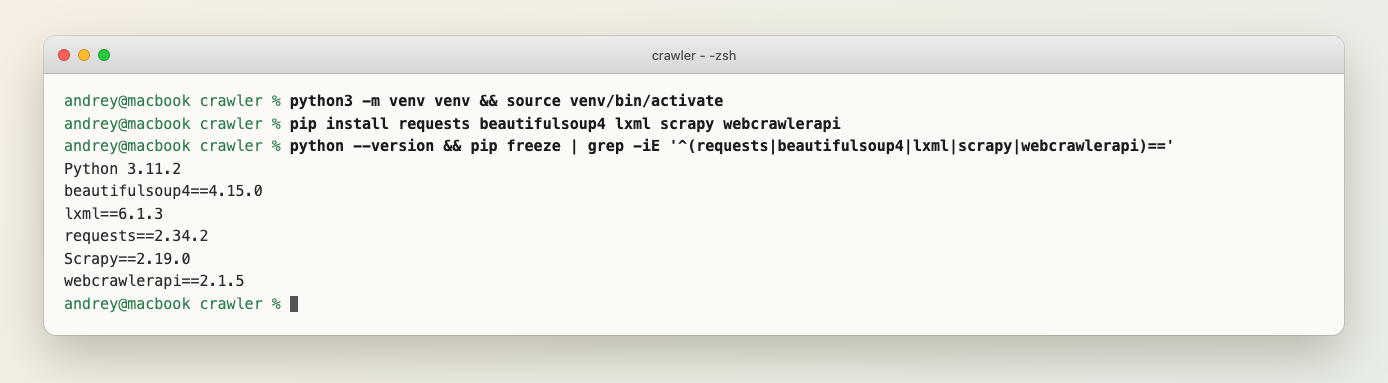
Python 3.11, one virtual environment, five packages:
The test sites are books.toscrape.com (about 1,000 books across 50 listing pages) and quotes.toscrape.com/js/ (quotes written by JavaScript). Both exist for people learning to scrape. Their robots.txt returns 404, which means no rules.
I still behaved. Every request carried an honest User-Agent, polite runs waited 0.5 seconds with one connection, and I kept the total under about 1,000 requests across all experiments (including a few reruns when I found my own mistakes). The "fast" configuration used 8 connections for 20 pages, three times. The API runs were capped at 19 HTTP calls in total, and I used 18.
Approach 1: A Python Web Crawler with requests and BeautifulSoup
This is the full working file. It covers the whole checklist: breadth-first queue, normalizing, a seen set, robots.txt, delay, retries with backoff, and a page limit. The --workers option fetches in small batches with threads.
"""Approach 1: a requests + BeautifulSoup crawler (BFS, dedup, robots, delay, retries)."""
import argparse
import time
from collections import deque
from concurrent.futures import ThreadPoolExecutor
from urllib.parse import urldefrag, urljoin, urlparse
from urllib.robotparser import RobotFileParser

import requests
from bs4 import BeautifulSoup

UA = "WebCrawlerAPI-blog-test/1.0 (+https://webcrawlerapi.com)"


def normalize(url):
    url, _ = urldefrag(url)  # drop #fragment
    return url[: -len("index.html")] if url.endswith("/index.html") else url


def load_robots(session, seed):
    rp, root = RobotFileParser(), "{0.scheme}://{0.netloc}".format(urlparse(seed))
    r = session.get(root + "/robots.txt", timeout=10)
    if r.status_code == 200:
        rp.parse(r.text.splitlines())
    else:
        rp.allow_all = True  # no robots.txt (404): everything is allowed
    return rp


def fetch(session, url, delay, retries=2, timeout=10):
    for attempt in range(retries + 1):
        time.sleep(delay)
        try:
            r = session.get(url, timeout=timeout)
            if r.status_code < 500:  # 200, 404, ...: do not retry
                return r
        except requests.RequestException:
            pass
        if attempt < retries:
            time.sleep(2 ** attempt)  # backoff: 1s, 2s, 4s
    return None


def crawl(seeds, max_pages=20, delay=0.5, workers=1, retries=2, dedup=True, norm=True, timeout=10):
    seeds = list(dict.fromkeys(normalize(s) for s in seeds)) if norm else seeds
    session = requests.Session()
    session.headers["User-Agent"] = UA
    robots = load_robots(session, seeds[0])
    host = urlparse(seeds[0]).netloc
    queue, seen, pages = deque(seeds), set(seeds), []
    with ThreadPoolExecutor(workers) as pool:
        while queue and len(pages) < max_pages:
            batch = [queue.popleft() for _ in range(min(workers, len(queue), max_pages - len(pages)))]
            batch = [u for u in batch if robots.can_fetch(UA, u)]
            for url, r in zip(batch, pool.map(lambda u: fetch(session, u, delay, retries, timeout), batch)):
                if r is None or r.status_code != 200:
                    continue
                soup = BeautifulSoup(r.text, "lxml")
                title = soup.h1.get_text(strip=True) if soup.h1 else ""
                pages.append({"url": url, "title": title, "status": r.status_code})
                for a in soup.select("a[href]"):
                    link = urljoin(url, a["href"])
                    link = normalize(link) if norm else link
                    if urlparse(link).netloc == host and not (dedup and link in seen):
                        seen.add(link)
                        queue.append(link)
    return pages


if __name__ == "__main__":
    p = argparse.ArgumentParser()
    p.add_argument("seed", nargs="+")
    p.add_argument("--max-pages", type=int, default=20)
    p.add_argument("--delay", type=float, default=0.5)
    p.add_argument("--workers", type=int, default=1)
    a = p.parse_args()
    t = time.perf_counter()
    result = crawl(a.seed, a.max_pages, a.delay, a.workers)
    secs = time.perf_counter() - t
    print(f"{len(result)} pages in {secs:.1f}s = {len(result) / secs:.2f} pages/sec")
Run it like this:
python crawl_loop.py https://books.toscrape.com/ --max-pages 20 --delay 0.5
It's 67 lines without comments and blank lines. 12 of them are the command line.
Normalizing URLs and Deduplication
Here's a thing I wanted to test. books.toscrape.com serves its home page at two addresses: / and /index.html. Nearly every page links to the second one. A crawler that compares raw strings sees two pages.
I seeded the crawl with both addresses, capped it at 12 pages, and counted fetches of the same page (same URL after removing #fragment and a trailing index.html):
| Setup | Pages fetched | Duplicate fetches |
|---|---|---|
| Loop, no seen set, no normalizing | 12 | 3 |
| Loop, seen set, no normalizing | 12 | 1 |
| Loop, normalizing + seen set | 12 | 0 |
| Scrapy defaults | 12 | 1 |
The cap is small, so the counts are small, and they grow with the crawl. A seen set stops loops. Normalizing merges aliases. You need both.
Scrapy's built-in duplicate filter dropped 626 repeated requests in that 12-page run, and still fetched both / and /index.html. It compares URLs, not pages. If a site has aliases, you normalize them yourself in the spider.
Respecting robots.txt and Rate Limiting
Python ships urllib.robotparser, and the loop above uses it. Here's what it does on a site with a simple rule. httpbin.org/robots.txt contains just User-agent: * and Disallow: /deny (I fetched the file once and did not crawl the site):
rp = RobotFileParser()
rp.parse(requests.get("https://httpbin.org/robots.txt", headers={"User-Agent": UA}).text.splitlines())
rp.can_fetch(UA, "https://httpbin.org/html")       # True
rp.can_fetch(UA, "https://httpbin.org/deny")       # False
rp.can_fetch(UA, "https://httpbin.org/deny/page")  # False
The defaults differ a lot between the three approaches:
| Checks robots.txt by default? | |
|---|---|
| Your own loop | Only if you write it |
| Scrapy, project from scrapy startproject | Yes (ROBOTSTXT_OBEY = True in the template) |
| Scrapy, a single file run with runspider | No (the global default is False) |
| Crawl API | No. respect_robots_txt defaults to false (see the docs) |
That last row is easy to miss, so set it. The same goes for the delay: Scrapy's project template sets DOWNLOAD_DELAY = 1 and one connection per domain, while a bare runspider file has no delay at all.
In the polite runs the loop waits 0.5 seconds before every request. It reached 1.3 pages per second, because the delay and the response time add up (about 15.4 seconds for 20 pages). Scrapy reached 1.6 because it overlaps the wait with the download.
Handling Errors and Retries
Real sites return 500s, time out and vanish. I wrote a small server (flaky_server.py, bound to 127.0.0.1 only) with four kinds of pages: 4 that always work, 4 that fail twice with a 500 and then work, 1 that sleeps 5 seconds, and 1 that returns 404. Timeout was 3 seconds in both tools. That makes 9 pages that can be fetched.
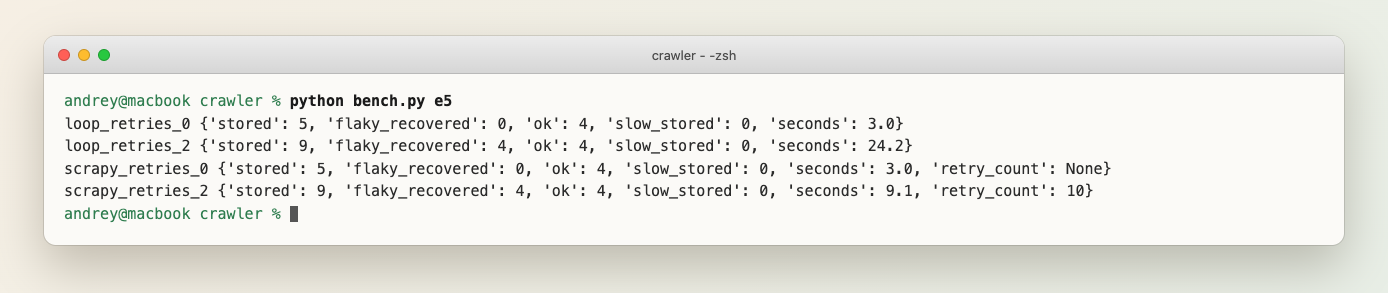
| Pages stored (of 9) | Flaky pages recovered | Time | |
|---|---|---|---|
| Loop, no retries | 5 | 0 | 3.0 s |
| Loop, 2 retries with backoff | 9 | 4 | 24.2 s |
| Scrapy, RETRY_TIMES=0 | 5 | 0 | 3.0 s |
| Scrapy, RETRY_TIMES=2 | 9 | 4 | 9.1 s |
Both recovered everything recoverable. The 5-second page was lost by everyone because it is slower than the 3-second timeout. A timeout is a choice.
The time column is the interesting part. My loop sleeps 1 and then 2 seconds between attempts (exponential backoff), and it does it one page at a time. Scrapy retried right away, with no backoff, which was faster here and would be rude on a real server that is struggling. If you use Scrapy, turn on AUTOTHROTTLE_ENABLED as well.
The retry logic is the fetch function in the file above: retry on 5xx and timeouts, wait 1, 2, 4 seconds, and give up after the last attempt. Don't retry a 404, it won't change.
Sitemap Shortcut
If the site has a sitemap, you can skip link discovery completely. You get the URL list in one request, and you avoid infinite calendars and filter pages.
"""List the URLs a site declares in /sitemap.xml (follows sitemap index files)."""
import sys
import xml.etree.ElementTree as ET
from urllib.parse import urljoin

import requests


def get_sitemap_urls(site: str) -> list[str]:
    urls, todo = [], [urljoin(site, "/sitemap.xml")]
    while todo:
        root = ET.fromstring(requests.get(todo.pop(), timeout=20).content)
        locs = [el.text.strip() for el in root.iter() if el.tag.endswith("loc") and el.text]
        (todo if root.tag.endswith("sitemapindex") else urls).extend(locs)
    return urls


if __name__ == "__main__":
    found = get_sitemap_urls(sys.argv[1])
    print(f"{len(found)} URLs, first: {found[0]}")
books.toscrape.com has no sitemap (404), so I tried it on our own site: it returned 283 URLs on the day I ran it. Sitemaps are often incomplete or missing, so treat this as a shortcut and not a guarantee. It's about 15 lines of standard library plus requests, written from scratch for this post.
Approach 2: A Scrapy Spider
Scrapy is a crawling framework. You describe what to do with a page, and it runs the queue, duplicate filter, retries, throttling and robots.txt. (It calls a crawler a "spider", so a "web spider python" search ends here.) The same crawl:
"""Approach 2: the same crawl as a Scrapy spider. Run it without a project:

scrapy runspider crawl_scrapy.py -O out.jsonl
"""
import scrapy


class SiteSpider(scrapy.Spider):
    name = "site"
    start_urls = ["https://books.toscrape.com/"]
    allowed_domains = ["books.toscrape.com"]  # stay on one site
    custom_settings = {
        "USER_AGENT": "WebCrawlerAPI-blog-test/1.0 (+https://webcrawlerapi.com)",
        "ROBOTSTXT_OBEY": True,
        "DOWNLOAD_DELAY": 0.5,
        "CONCURRENT_REQUESTS": 1,  # the default is 16 and they all finish after a stop
        "RETRY_TIMES": 2,
        "DOWNLOAD_TIMEOUT": 10,
        "CLOSESPIDER_PAGECOUNT": 21,  # stop rule: 20 pages + the robots.txt response
    }

    def parse(self, response):
        yield {
            "url": response.url,
            "title": response.css("h1::text").get(default=""),
            "status": response.status,
        }
        # response.follow resolves relative URLs for us; Scrapy drops repeats
        yield from response.follow_all(css="a", callback=self.parse)
Run it without creating a project:
scrapy runspider crawl_scrapy.py -O out.jsonl
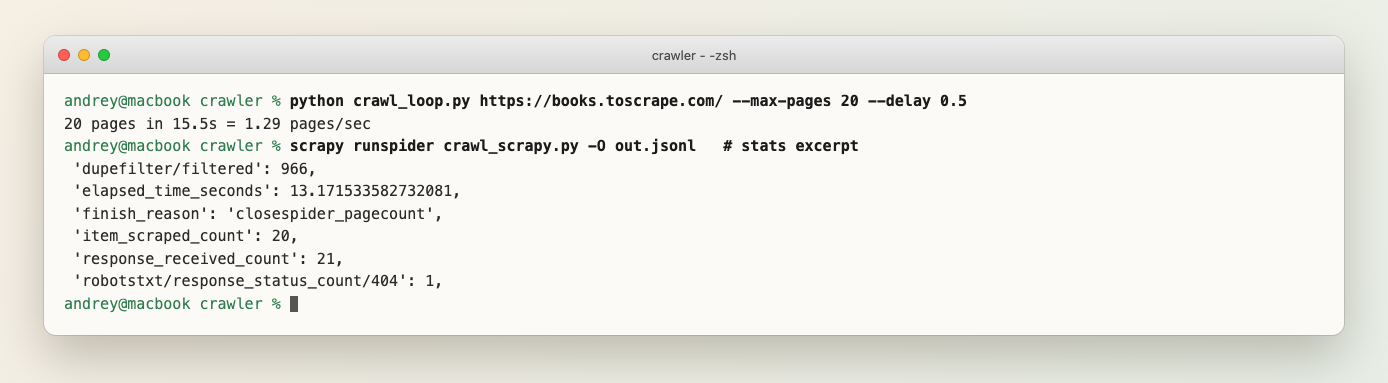
That's 24 lines. The same job is 67 in the loop. A project made with scrapy startproject adds a settings file (8 live lines) and several files you don't need for a small job.
What Scrapy Does for You
- Duplicate filter: every request is fingerprinted. Exact repeats are dropped (966 of them in the 20-page polite run).
- Retries: failed requests are retried, as shown above.
- Throttling and concurrency: DOWNLOAD_DELAY, CONCURRENT_REQUESTS and AUTOTHROTTLE_ENABLED.
- Robots.txt: one setting.
- Stop rule: CLOSESPIDER_PAGECOUNT.
Two gotchas from my runs. First, CLOSESPIDER_PAGECOUNT counts the robots.txt response too, so I set it to 21 to get 20 pages. Second, it doesn't kill requests already in flight. With the default of 16 concurrent requests, my first "20 page" run stored 35 pages. Setting CONCURRENT_REQUESTS to 1 fixed it for the polite run. In the fast run (8 connections) it still fetched 27 pages, so I report pages per second, not a clean 20-page time.
Relative URLs: response.follow and urljoin
Links in HTML are often relative (../book/index.html). In Scrapy you don't need to fix them yourself. response.follow and response.follow_all resolve them against the current page. If you need an absolute URL as a string, use response.urljoin(href). In the loop approach, the same job is done by urllib.parse.urljoin, which is already in the code above.
Where Scrapy Costs You
- A new mental model: callbacks, settings, an event loop underneath.
- Settings that are easy to get wrong (see the robots.txt table above).
- No JavaScript rendering. A plain Scrapy spider sees the same HTML as requests.
If you pick Scrapy, this Scrapy tutorial builds the full version: link rules, a pipeline that saves each page, and scrapy-playwright for JavaScript pages.
Approach 3: A Python Web Crawler with the Crawl API
The third option is to not run a crawler. You send a start URL and some limits, and a job crawls and returns the pages. Here's the same crawl through the Python SDK:
"""Approach 3: the same crawl through the WebCrawlerAPI Python SDK (pip install webcrawlerapi)."""
import os
import time

from webcrawlerapi import WebCrawlerAPI

crawler = WebCrawlerAPI(api_key=os.environ["WEBCRAWLER_API_KEY"])  # never hard-code the key

start = time.perf_counter()
job = crawler.crawl_async(
    url="https://books.toscrape.com/",
    items_limit=20,                # stop rule: 20 pages
    output_formats=["markdown"],
    respect_robots_txt=True,       # the API default is False
)

# crawl() would poll for you; this loop is the same thing, with a visible poll count
polls = 0
while True:
    time.sleep(4)
    job = crawler.get_job(job.id)
    polls += 1
    if job.is_terminal or polls >= 10:
        break

secs = time.perf_counter() - start
done = [i for i in job.job_items if i.status == "done"]
print(f"status={job.status} pages={len(done)} polls={polls} wall={secs:.1f}s")
print(done[0].original_url, done[0].markdown_content_url)
I used crawl_async and a counted get_job loop instead of crawler.crawl(...), because crawl() polls inside the SDK (up to 100 times) and I wanted a hard cap on my calls. In a normal script, crawl() is one line.
The parameters map onto the checklist from earlier:
| Concern | Hand-rolled | Scrapy | API parameter |
|---|---|---|---|
| Stop rule | counter | CLOSESPIDER_PAGECOUNT | items_limit |
| Depth | track it per URL | DEPTH_LIMIT | max_depth |
| URL filter | regex in the loop | LinkExtractor | whitelist_regexp, blacklist_regexp |
| Robots.txt | robotparser | ROBOTSTXT_OBEY | respect_robots_txt |
| Output | parse HTML yourself | write a callback | output_formats (markdown, html, ...) |
Full parameter list: crawl API docs. The landing page Python web crawler API has the short version, and web scraping API covers single pages.
What I Measured
I ran the 20-page books.toscrape crawl 4 times. Three finished fast: the job's own timestamps show 2.5 to 2.6 seconds from creation to finish (20 pages, about 7.8 pages per second), and the first poll saw "done" at 4.4, 6.5 and 26.5 seconds of wall clock (my poll timing was crude, so use the server clock). One run was an outlier: at 25 seconds it had 15 of 20 pages and was still running, and I had no calls left to wait for it.
So, in short: faster than my polite loop, slower than the 8-connection local runs, and with a long tail I saw once in four runs. The API sets its own pace. I can't give it a 0.5 s delay, and I did not test how it behaves on a site that pushes back.
It also returned both https://books.toscrape.com/ and https://books.toscrape.com/index.html in every run. Duplicates are not fully removed for you.
For the failure case, I crawled a missing page. The item came back with status: error, page_status_code: 404 and error_code: host_returned_error, which is documented on the errors page. The API cannot reach localhost, so my flaky server test only applies to the two local tools. The docs don't describe automatic retries for crawl jobs, so I'm not claiming any.
Cost
Pricing is per crawled page: $0.002 on pay-as-you-go, $0.0015 and $0.001 on higher plans (pricing). That's $2 per 1,000 pages at the base rate. My whole test (about 80 successful pages) came to roughly $0.16 by the per-item cost fields. I did not audit the billing dashboard.
One odd detail: the pricing docs say you only pay for successful requests, yet the single failed item in my test (the 404 page) showed a cost of $0.002 in its cost field. I don't know whether that is only a display value or an actual charge, so check your own billing before relying on either statement.
What the API Doesn't Do
- It returns HTML or Markdown per page. Custom per-page extraction (price, SKU, author) is your code, run after.
- It cannot crawl localhost or a private network.
- respect_robots_txt is off unless you set it.
- It costs money per page. A loop costs you an afternoon.
The async mode can also call a webhook when the job ends, so you don't have to poll.
Speed and Code Size, Side by Side
What the three results say:
- Polite crawling is slow, whatever you use. A 0.5 s delay caps you near 1.5 pages per second, so 1,000 pages take about 11 minutes.
- Without a delay, Scrapy beat my loop (19.8 vs 13.0 pages per second). I think the loop loses time because each batch waits for its slowest page. Both are far faster than a polite crawl, and a real site may block you long before you get the benefit.
- Code size: 67 lines for the loop, 24 for Scrapy, 23 for the API script. Scrapy's lines hide a framework, and the API's lines hide a service.
Not tested: proxies, CAPTCHAs, anti-bot pages, logins, sites over 50 pages, async clients like httpx.
Crawling JavaScript-Heavy Websites with Python
Here's the case where both local tools fail quietly. quotes.toscrape.com/js/ loads its quotes with JavaScript. The HTML that comes back has none.
"""Count quotes on a JavaScript-rendered page with requests + BeautifulSoup (no browser)."""
import requests
from bs4 import BeautifulSoup

URL = "https://quotes.toscrape.com/js/"
r = requests.get(URL, headers={"User-Agent": "WebCrawlerAPI-blog-test/1.0 (+https://webcrawlerapi.com)"}, timeout=10)
soup = BeautifulSoup(r.text, "lxml")
print(f"HTTP {r.status_code}, {len(r.text)} bytes, quotes found: {len(soup.select('div.quote'))}")
print("script tags:", len(soup.find_all('script')))
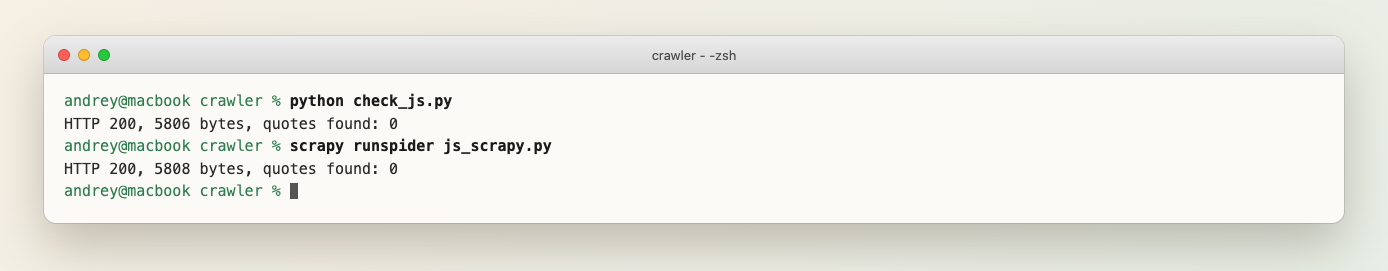
HTTP 200, 5.8 KB of HTML, 0 quotes, for both requests and Scrapy. No error. That's why "my crawler returns empty pages" is such a common question. Nothing failed. The content just isn't there yet.
The crawl API, on a 10-page crawl from the same URL, returned Markdown for the /js/ page with content in it (676 characters in the item I measured). That tells me the page was rendered, but I did not save the text, so I can't give you an exact quote count. Your options:
| Option | What it takes |
|---|---|
| Drive a browser (Playwright) | Slow and heavy, but full control. See web scraping with Playwright |
| Scrapy plus a browser plugin | Keeps Scrapy's queue, adds a browser. I didn't test this combination |
| A crawl API that renders | No browser to run. See also the glossary on JavaScript-heavy sites |
For the rendering side in depth, read the JavaScript rendering guide. For Node.js, see web scraping with JavaScript.
Quick check: view the page source and search for a sentence you see on screen. If it's missing, plain HTTP won't see it.
Which One to Pick
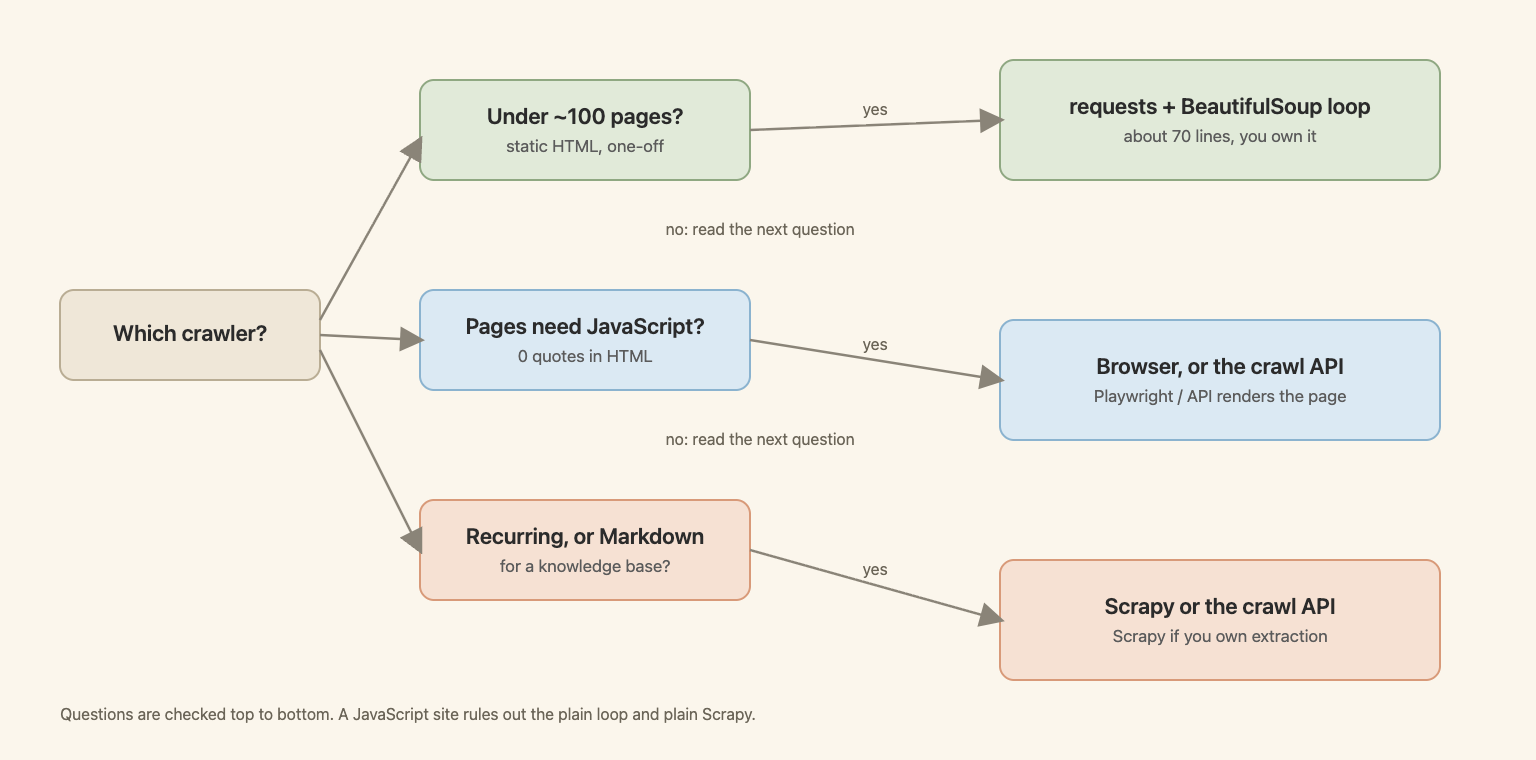
| Loop | Scrapy | API | |
|---|---|---|---|
| Pages | Up to a few hundred | Thousands and up | Any, you pay per page |
| JavaScript sites | No | No | Yes (rendered content came back, see above) |
| Recurring crawls | You run the scheduler | You run the scheduler | Job API and webhooks |
| You control extraction | Fully | Fully | After the crawl |
| Output | Anything you parse | Items (JSON, CSV) | Markdown or HTML per page |
| Ongoing work | Highest per feature | Medium | Lowest |
| Cost | Your time | Your time and servers | $0.001 to $0.002 per page |
What I'd do:
- 50 pages of static HTML, once: write the loop. An API is not worth it.
- You need custom fields from thousands of pages: Scrapy, and own the infrastructure.
- The pages need rendering, or you feed an AI knowledge base and want clean Markdown: the API saves the most time.
The trade-off is covered in more depth in build a crawler or use a crawling API. Other open-source options, such as Crawl4AI, are in best open source web crawlers and web crawler with Crawl4AI. For scraping libraries by speed, see best Python web scraping libraries. If you're picking a language first, there's Python vs Node.js for web crawling.
Legal and Polite Crawling
robots.txt is a convention, not permission. Respect it, send an honest User-Agent, wait between requests and keep concurrency low. Terms of service and the kind of data (personal data especially) matter more than any file. I covered the details in web scraping ethics and the glossary entry is web crawling legal. Blocking is a separate topic (how to avoid getting blocked), and I didn't test it here.
Frequently Asked Questions
Which is better, Scrapy or BeautifulSoup?
They do different jobs. BeautifulSoup parses one HTML page. Scrapy is a framework that fetches, queues, retries and exports, and a spider can use BeautifulSoup inside. A requests loop is quicker to learn for a small crawl; Scrapy saves you from writing the queue, retries and throttling in a big one.
Is a web crawler illegal?
Crawling public pages is generally allowed, but laws and terms differ by country and site, and personal data has extra rules. I'm not a lawyer. Start with is web crawling legal and web scraping ethics.
Do I need Scrapy to build a Python web crawler?
No. A loop of about 70 lines crawled 20 pages fine, with dedup, robots.txt and retries. Scrapy starts to pay off when the crawl gets big or you want throttling and a stop rule without writing them.
How do I stop a Python crawler from visiting the same URL twice?
Keep a set of URLs you've already queued, and normalize before checking: drop the #fragment and map aliases like /index.html to /. In my test a seen set alone still let one duplicate through, and Scrapy's filter did the same.
Why does my Python crawler return empty pages?
Usually JavaScript writes the content, so it isn't in the HTML you downloaded. Both requests and Scrapy gave me HTTP 200 and 0 quotes on a JavaScript page. Check the page source. If the text isn't there, you need a browser or a rendering API (see web scraping with Python and the Playwright guide).
How fast can a Python web crawler run politely?
With a 0.5 second delay and one connection, I measured 1.3 pages per second for the loop and 1.6 for Scrapy. A 1,000 page site takes roughly 10 to 13 minutes. Without delays and with 8 connections I saw 13 and 20 pages per second, but that is not polite on a site you don't own.
Try It Yourself
- Run the files from this post (crawl_loop.py, crawl_scrapy.py, crawl_api.py) against a practice site. Keep the delay.
- Read the crawl API docs and the Python SDK page if you want the API route.
- To see the same crawl in a few lines, there's the Python web crawler page. For single pages, there's Python scraper.
All numbers come from runs in October 2026 (versions are in the screenshot above). Your numbers will differ with your network and the site's mood.