How to Enrich Company Data from Partial Records
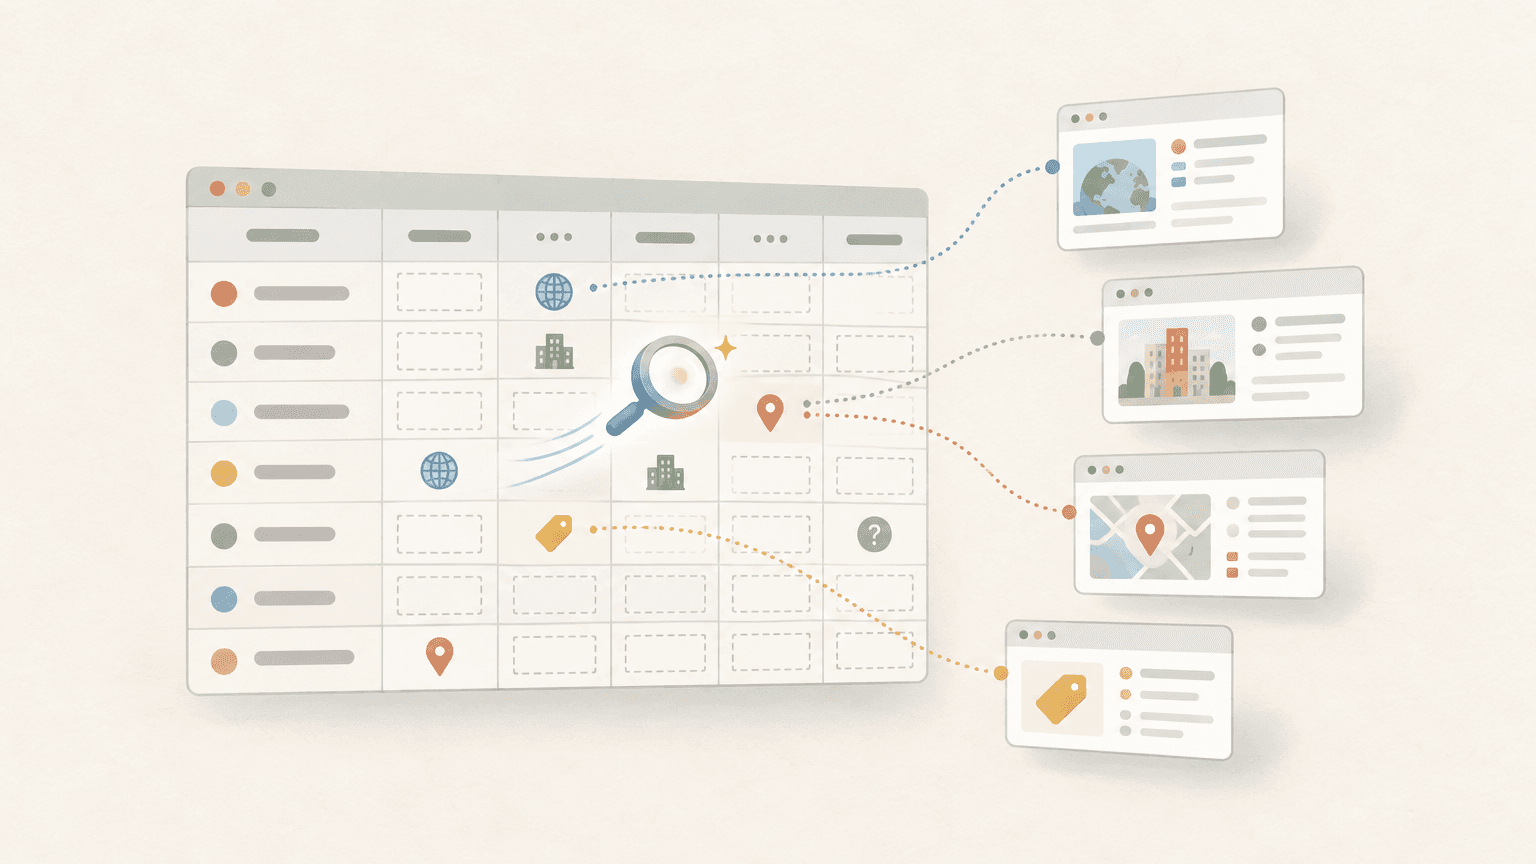
You have a list of companies, and every row is incomplete. Some rows have a name and a city. Some have a website and nothing else. Some have an industry that's plainly wrong.
You need the same set of fields for all of them: website, what they do, industry, location, a contact page.
Enrichment tools can help, but they return whatever is already in their database. They charge per record, the data is often months old, and small or niche companies are usually missing.
There's another way. Send what you know to WebCrawler Agent, and get back only the missing fields, each with a source URL.
curl --request POST \
  --url https://api.webcrawlerapi.com/v1/agent \
  --header 'Authorization: Bearer <YOUR_API_KEY>' \
  --header 'Content-Type: application/json' \
  --data '{
    "prompt": "Research the company below. Known data: name=Northwind Logistics, city=Rotterdam, country=Netherlands, website=null, industry=null, description=null. Find the official website and fill ONLY the null fields. Every value must include the source URL. If you cannot confirm a value, return not_found. Do not guess.",
    "max_spend_usd": 0.5
  }'
What partial-data enrichment means
Enrichment means adding missing fields to a record you already have. Partial-data enrichment means working from whatever fields exist, and those fields are different for every row.
A few rules make it work:
- Fill the gaps. Only research what's empty.
- Keep what's known. Don't overwrite good data.
- Flag what looks wrong. A "Retail" label on a tooling manufacturer should come back as a correction, not stay silent.
- Never invent. An empty cell is better than a wrong one.
Here's what you can realistically get from different starting points:
| What you have | What you can get |
|---|---|
| Name + city | Website, description, industry, address, contact page |
| Website only | Name, description, products/services, industry, countries served |
| Name + address + industry | Verified or corrected values |
So why not just use a data enrichment tool? For many lists, fixed-field databases fall short:
- Stale data. The record was collected once and refreshed whenever.
- Fixed field list. You get the columns they have, not the ones you need.
- Weak coverage. Small, local, and non-US companies are often missing or thin.
- No custom questions. You can't ask "do they sell to hospitals?" and get an answer.
How it works
One agent run per record. The prompt carries the known fields, the fields to fill, and the rules.
- You send a POST with the prompt, a budget (max_spend_usd), and optionally an output_schema.
- The agent searches the web, then opens the company's own site: homepage, About, Contact, Careers.
- You poll GET /v1/agent/job/{id}. When status is done, the result is in data.
You don't need any URLs. A name and a city are enough to start. Finding the right website is step one, and I covered it in detail in how to find a company website.
If you already have the website, pass it in urls. It's cheaper, and there's no risk of the agent picking the wrong company with the same name.
Use output_schema to keep every row in the same shape. That way results go straight into a spreadsheet or database without cleanup.
What you can fill
Firmographic data is company-level attributes: industry, location, size, and similar facts. Public websites reveal some of these well and some not at all.
Fields that work well from public sources:
- Official website
- Legal or full company name
- One-line description
- Products and services
- Industry (a plain label, or a NAICS/SIC candidate)
- HQ address
- Countries or regions served
- Target customers (B2B or B2C, segments)
- Contact page or general email (more on that in finding contact emails on a website)
- Careers page and hiring signal
- Social profiles
Size is the tricky one. A website might say "a team of 40" or might say nothing. Revenue is almost never there.
Writing a good prompt
The prompt is where bulk enrichment becomes trustworthy or turns into noise. What I've found helps:
- Give every known field, even if you suspect it's wrong. Many companies share a name. A city and an industry narrow the search a lot.
- Mark known and empty fields. Use null for empty ones and say explicitly: "fill only the null fields."
- Ask for a source URL per value. Now every cell is checkable.
- Allow "not_found" and "uncertain". Say "don't guess." This single line matters more than anything else when you run thousands of rows.
- Ask for a status per field when verifying: confirmed, corrected, or uncertain.
- Keep the output field-shaped. "Tell me about the company" gives unpredictable output. A list of named fields doesn't.
Prompt templates
Five templates. You don't need all of them. Pick the one that matches your data.
1. Name + location to full profile
Use this when you have a name and a location, and most other columns are empty.
{
  "prompt": "Research the company below. Known data: name='Northwind Logistics', city='Rotterdam', country='Netherlands', website=null, industry=null, description=null. Find the official website and fill ONLY the null fields. Every value must include the source URL. If you can't confirm a value, return \"not_found\". Don't guess and don't change known fields.",
  "max_spend_usd": 0.5,
  "output_schema": {
    "type": "object",
    "properties": {
      "website":      { "type": "string" },
      "industry":     { "type": "string" },
      "description":  { "type": "string" },
      "hq_address":   { "type": "string" },
      "contact_page": { "type": "string" },
      "confidence":   { "type": "string", "enum": ["confirmed", "uncertain", "not_found"] },
      "sources":      { "type": "array", "items": { "type": "string" } }
    }
  }
}
2. Website only to company profile
Use this when all you have is a domain.
{
  "prompt": "From this company's own website, extract: company name, one-sentence description, main products or services, industry, target customers (B2B/B2C and segments), countries served, and whether they are hiring (careers page). Cite the page each fact came from.",
  "urls": ["https://example.com"],
  "max_spend_usd": 0.5
}
3. Verify and correct an existing record
Use this when the data is there but you don't trust it.
{
  "prompt": "Verify this company record using the company's official website: name='Acme Tooling GmbH', address='Industriestr. 5, Stuttgart', industry='Retail'. For each field return: current value, verified value, status (confirmed | corrected | uncertain), and evidence URL. Don't overwrite a field unless the website clearly shows a different value.",
  "max_spend_usd": 0.5
}
4. Industry classification (NAICS)
Use this when you need a consistent industry code across the list.
Based on the official website of {company_name} ({city}, {country}), suggest the most likely NAICS code and title. Explain in one sentence which products or services justify it. If the business spans several activities, return up to 3 candidates ranked by likelihood.
Treat the code as a candidate for review, not an official registration.
5. Company research brief
Use this when you need a quick read on a company before a call or a decision, not just table fields.
Research {company_name} ({website}). Return 5 bullets: what they sell, who they sell to, recent news or launches from their site or blog, platforms or technologies they mention, and the best public contact channel. Include a source URL for each bullet.
Adjust the fields to your list. The structure stays the same.
Running it on a whole list
The loop is simple: build a prompt from each row (only the known fields), start a run, poll, write data back to new columns.
Here's a minimal Node 18+ version. No libraries, only fetch. It assumes you've already parsed your CSV into an array of objects.
const API = "https://api.webcrawlerapi.com/v1/agent";
const headers = {
  Authorization: `Bearer ${process.env.WEBCRAWLER_API_KEY}`,
  "Content-Type": "application/json",
};

// rows: [{ name: "Northwind Logistics", city: "Rotterdam", website: null, industry: null }, ...]
async function enrich(row) {
  // Pass every field: known values narrow the search, nulls mark the gaps
  const prompt = `Research the company below. Known data: ${JSON.stringify(row)}. ` +
    `Fill ONLY the null fields. Include a source URL for every value. ` +
    `If you can't confirm a value, return "not_found". Don't guess.`;

  const body = { prompt, max_spend_usd: 0.5 };
  if (row.website) body.urls = [row.website]; // known site = cheaper and no wrong-company risk

  const run = await fetch(API, { method: "POST", headers, body: JSON.stringify(body) }).then(r => r.json());

  // Poll until the run finishes
  while (true) {
    await new Promise(r => setTimeout(r, 5000));
    const job = await fetch(`${API}/job/${run.id}`, { headers }).then(r => r.json());
    if (job.status === "done") return { ...row, enriched: job.data };
    if (job.status === "error" || job.status === "canceled") return { ...row, error: job.error_reason };
  }
}

const results = [];
for (const row of rows) results.push(await enrich(row)); // sequential keeps it easy to watch
Or use the JS SDK. runAgent starts the run and polls it for you, so the loop gets shorter:
npm i webcrawlerapi-js
import webcrawlerapi from "webcrawlerapi-js";

const client = new webcrawlerapi.WebcrawlerClient(process.env.WEBCRAWLER_API_KEY);

async function enrich(row) {
  const run = await client.runAgent({
    prompt: `Research the company below. Known data: ${JSON.stringify(row)}. ` +
      `Fill ONLY the null fields. Include a source URL for every value. ` +
      `If you can't confirm a value, return "not_found". Don't guess.`,
    urls: row.website ? [row.website] : undefined,
    max_spend_usd: 0.5,
  });

  // runAgent returns once status is done, error, or canceled
  return run.status === "done"
    ? { ...row, enriched: run.data }
    : { ...row, error: run.error_reason };
}
A few things I'd do before running a full list:
- Set max_spend_usd per record. One hard-to-find company can't eat your whole budget. The 0.5 above is a placeholder, tune it on your data.
- Try 10 to 20 rows first. Check the results by hand, adjust the prompt, then run the rest.
- Filter uncertain and not_found rows into a manual review queue instead of trusting everything.
- Pass urls when the website is known. Faster, cheaper, more reliable.
- Pick the model for the job. A cheaper model is fine for simple fills. Use a stronger one for classification or verification.
What you won't get
Honest limits:
- Data that isn't public. Revenue, exact headcount, private ownership, personal contact details.
- Companies with no website or an almost empty one. Expect not_found.
- Very common names with no location. "Atlas Group" alone is ambiguous. Add a city or an industry.
- Guaranteed accuracy. Sources make results checkable, not automatically correct.
- The cheapest price at huge volume for simple fields. If a database already has the exact field you need and it's fresh enough, a database lookup can cost less.
FAQ
Is this a Clay alternative? For the research part, yes. Instead of a per-seat platform, you call one API with your own prompt and fields. It isn't a contact database or an outreach tool.
How accurate is it? It depends on what's public. Source URLs and "not_found" rules make every value verifiable, so you can check the ones that matter.
Do I need to give it URLs? No. A name and a location work. A website makes it faster and more reliable.
Can I choose the fields? Yes. Any field you can describe in the prompt or in output_schema.
Wrapping up
Partial records in, only the gaps filled, a source for every value. That's the whole idea.
If you're new to agents in general, what an AI crawl agent is explains how they decide what to read. For a real production example of one agent prompt running across many sites, see how CoffeeHunt tracks 67 roasters.
Grab an API key, try one record, then run the list. Full Agent API docs are here.
The same agent also handles narrower tasks: finding a company website by name, pulling contact emails from any website, finding customers of a SaaS company, or extracting SaaS pricing.